Every Yuneta release is measured before it is tagged, and a release that moves a lot of code ships a performance report. This page keeps the history: the trend of the main figures, report after report, and a link to each report.
Two kinds of figures are kept:
A/B figures. The same benchmark, built with the module of the new release and with the module of the release before, the two binaries run alternately on one machine. They say what the release changed. A change inside the spread of its rounds is noise, and it is called noise.
Absolute figures. The benchmarks run on the build of the release at tag time. They say what one machine does with the release: records stored per second, messages per second, what one operation costs.
A figure that got slower is never left out. It is shown with its reason, as the CHANGELOG states it: most are the price of a guarantee (a file that survives a power cut, a record that reaches the disk before a command runs), kept by decision.
Reports
| Release | Against | Report | Rendered | Raw figures |
|---|---|---|---|---|
| 7.26.0 | 7.25.22 | 7.26.0.html | view | 7.26.0.json |
| 7.25.22 | 7.25.21 | 7.25.22.html | view | 7.25.22.json |
| 7.25.21 | 7.25.20 | 7.25.21.html | view | 7.25.21.json |
| 7.25.20 | 7.25.5 | 7.25.20.html | view | 7.25.20.json |
| 7.25.5 | 7.25.4 | 7.25.5.html | view | 7.25.5.json |
The report is one self-contained page (no script, no external file). GitHub
shows it as source code; the “view” link renders it. How a report is made, and
the schema of its .json, are in
performance/reports/README.md.
The trend
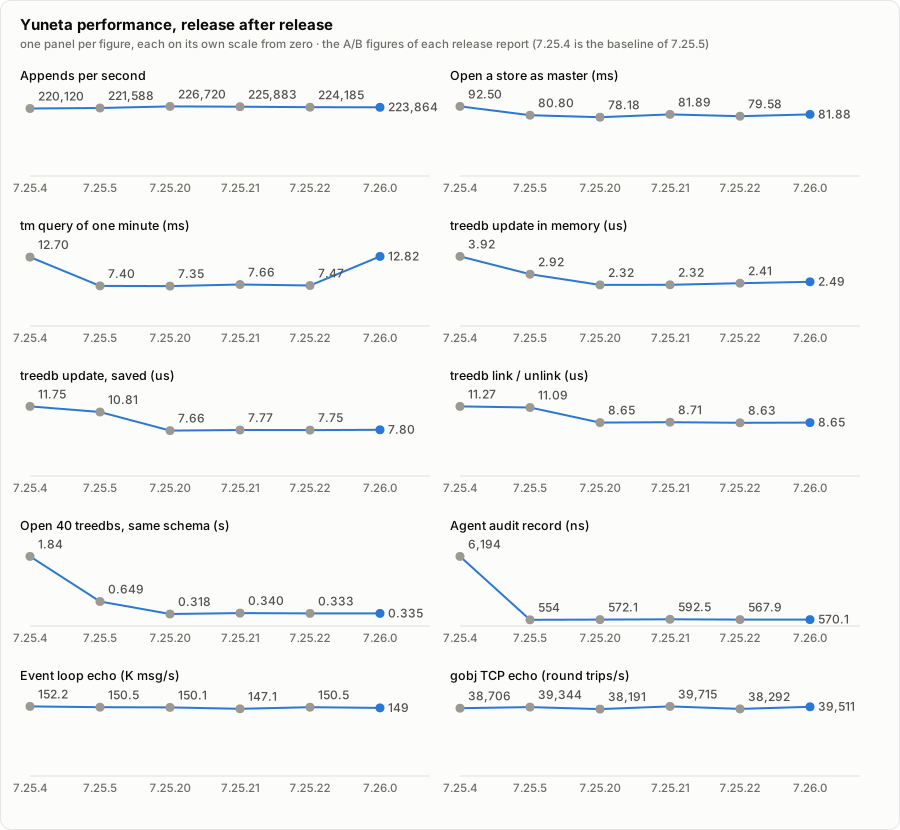
The main A/B figures, one panel each, on their own scale from zero. The first report (7.25.5) gives two points: 7.25.4, its baseline, and 7.25.5. Each new report adds one point.
The C_TREEDB open of 7.25.5 compares two separate runs: 7.25.4 (medians of an earlier run) and 7.25.5 as shipped (the tag-time run). Every other point of the table comes from one alternated A/B run. Each point is the figure its own report measured, so two neighbouring points come from two runs, days apart: the A/B of 7.25.20 measured 7.25.5 again, the A/B of 7.25.21 measured 7.25.20 again, the A/B of 7.25.22 measured 7.25.21 again, and the A/B of 7.26.0 measured 7.25.22 again; their figures are in the sections below. Between two such reports a figure can move by a few percent with no change of the code (the master open of 7.25.20 measured 78.2 ms in its own report and 82.4 ms in the A/B of 7.25.21, another day): read a trend against the A/B of its report.
| Figure | Unit | 7.25.4 | 7.25.5 | 7.25.20 | 7.25.21 | 7.25.22 | 7.26.0 |
|---|---|---|---|---|---|---|---|
Appends per second (test_topic_pkey_integer, 4 link layouts) | appends/s | 220,120 | 221,588 | 226,720 | 225,883 | 224,185 | 223,864 |
Open a store as master, 20 000 md2 files (perf_timeranger2) | ms | 92.5 | 80.8 | 78.2 | 81.9 | 79.6 | 81.9 |
| A tm query of one minute of a key | ms | 12.7 | 7.4 (migrated) | 7.35 | 7.66 | 7.47 | 12.8 (every row) |
treedb: update a node in memory (perf_tr_treedb) | us | 3.92 | 2.92 | 2.32 | 2.32 | 2.41 | 2.49 |
| treedb: update a node and save it | us | 11.75 | 10.81 | 7.66 | 7.77 | 7.75 | 7.80 |
| treedb: link or unlink two nodes | us | 11.27 | 11.09 | 8.65 | 8.71 | 8.63 | 8.65 |
C_TREEDB: open 40 treedbs whose schema did not change (perf_c_treedb) | s | 1.84 | 0.649 | 0.318 | 0.340 | 0.333 | 0.335 |
One agent audit record of 300 bytes (perf_rotatory) | ns | 6,194 | 554 | 572 | 593 | 568 | 570 |
Event loop echo, 1 KB messages (perf_yev_ping_pong) | K msg/s | 152.2 | 150.5 | 150.1 | 147.1 | 150.5 | 149.0 |
TCP echo through the gobj stack (perf_tcp_test4) | round trips/s | 38,706 | 39,344 | 38,191 | 39,715 | 38,292 | 39,511 |
The appends of 7.25.20, 7.25.21, 7.25.22 and 7.26.0 are measured on whole-release builds (see below), not on the four padded links of 7.25.5. The tm query of 7.25.5 to 7.25.22 is the one of a topic its release had marked; 7.26.0 has no tm markers and reads every row of the key (a topic 7.25.22 had not marked took 402 ms).
What each figure means
| Figure | What it tells a user |
|---|---|
| Appends per second | How many records one yuno stores per second in a key-indexed timeranger2 topic. It is the write rate of every history, queue and log that Yuneta keeps on disk. |
| Open of a store | The start-up time of a yuno that owns a store (master) or follows one that another yuno writes (replica). |
| tm query | A read of a time range of a key: what a dashboard or a report pays to load one minute of data. |
| treedb update, link, create, delete | The cost of one change in the graph database: a node changed in memory, a node changed and saved, a relation made or undone, a node created or removed. The CPU time of the process, per operation. |
| C_TREEDB open | The start-up of a yuno with many treedbs. With an unchanged schema it is the everyday case; the first open (seed) and the open with a newer schema are one-time costs. |
| Agent audit record | What every command sent to the agent pays to be audited. |
| Log record | What a yuno pays for one line of its log file. |
| Event loop echo | The ceiling of the io_uring event loop alone: 1 KB messages echoed per second, no gobj layer. |
| gobj TCP and TLS echo | Round trips of a JSON message through the whole stack (C_IOGATE, C_TCP_S, C_PROT_TCP4H, C_CHANNEL), plain and encrypted, with and without a timeranger2 append per message. |
| Publish | gobj_publish_event(): one event delivered to N subscribers of one gobj, the in-process message bus. |
| Binary size | Each yuno is one fully static executable. The size includes OpenSSL and the whole framework. |
7.26.0 against 7.25.22
7.26.0 changes how timeranger2 reads and how its followers hear deletes: the
md2 rows of a scan are read 1024 at a time with one pread(), and the match
condition is parsed once per scan; the tm markers of 7.25.5..7.25.22 are gone,
so a tm condition filters every row of any topic; a key delete reaches the
rt_disk followers with the master’s delete sequence; and a link in a treedb
publishes the relationship (with_link_events on by default), not the parent
collapsed whole.
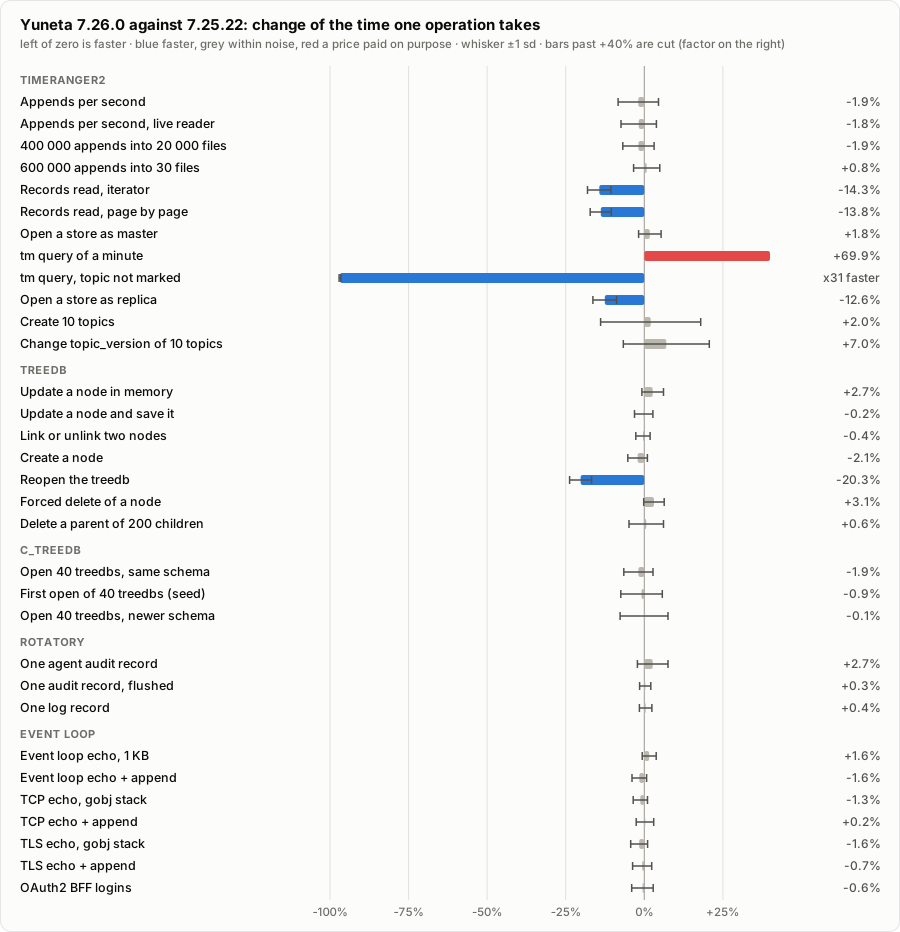
One bar per figure: the change of the time one operation takes, left of zero is faster. Blue is faster, red is a price paid on purpose, grey is within the noise of its rounds.
| Faster | 7.25.22 | 7.26.0 | Change | Why |
|---|---|---|---|---|
| A tm query of one minute, a topic 7.25.22 had not marked (1 key, 30 files x 20 000 rows) | 401.6 ms | 12.8 ms | -96.8%, 31x (t = -45) | The md2 rows read 1024 at a time with one pread() (an lseek() and a read() each before), and the match condition parsed into a C struct once per scan (~15 json lookups per row before). |
Records read per second, every record of 2 keys (test_topic_pkey_integer_iterator2) | 184,338 | 215,157 | +16.7% (t = 17) | The same two changes. |
Records read per second, page by page (test_topic_pkey_integer_iterator5) | 166,017 | 192,697 | +16.1% (t = 19) | The same two changes, on the read of a GUI. |
treedb: open (per node loaded, perf_tr_treedb reopen) | 390.3 us | 311.2 us | -20.3% (t = -15) | A treedb loads its topics through the same scans. |
| Open a store as a replica, 20 000 md2 files | 108.4 ms | 94.8 ms | -12.6% (t = -8.7) | The load no longer looks for a tm marker beside each md2 file: the markers are gone. The master’s open did not move. |
| Price | 7.25.22 | 7.26.0 | Change | What it buys |
|---|---|---|---|---|
| A tm query of one minute, a topic 7.25.22 had marked | 7.55 ms | 12.8 ms | +69.9% (t = 16) | The tm markers are gone (an API removal): a tm condition filters every row and no file is skipped by its tm range, correct on any topic and after any rollback. The block reads keep it at 1.7x the marked topic, not the 53x of an unmarked one. |
Fixed before the tag: a master that opens a topic makes its delete_seq.json
(the record of the delete sequence, which a follower takes as the sign that
its master signals each delete in order). Written durably -- a file fsync, a
rename and a directory fsync per topic -- it doubled the creation of 10
topics (131.4 -> 258.5 ms) and made the first open of 40 treedbs (400 topics)
55% longer (10.42 -> 16.19 s). It holds 0 and is made again if lost, so it is
written NOT durably now: 134.0 ms and 10.33 s, within the noise of 7.25.22
(the 7.26.0 side measured again after the fix, 8 rounds).
Not measured: a key delete on a topic with an rt_disk feed. No benchmark deletes keys under a feed; by construction such a delete writes the record of its sequence first, two fsyncs and a rename more than 7.25.22 did. A topic without feeds pays nothing.
Every other figure moved inside its spread (|t| < 3), on paths that changed or not. The binaries are 0.04-0.15% larger (stripped).
The method: 7.25.22 and 7.26.0 each built from their own tree (a git worktree
of the 7.25.22 tag with the same .config and compiler, where only the kernel
libraries, the modules, performance/c/ and the three ctest binaries were
built), the two binaries of each benchmark run alternately, the order flipped
every round, with a sync and a 3 s pause before each run: 8 rounds, 24 for
the three timeranger2 ctest binaries. outputs_ext was shared: linux-ext-libs
did not change. The treedb figures are CPU time of the process.
What one machine does with 7.26.0
The 7.26.0 side of the same run: 8 rounds (24 for the ctest binaries), mean of the rounds, on the machine described below.
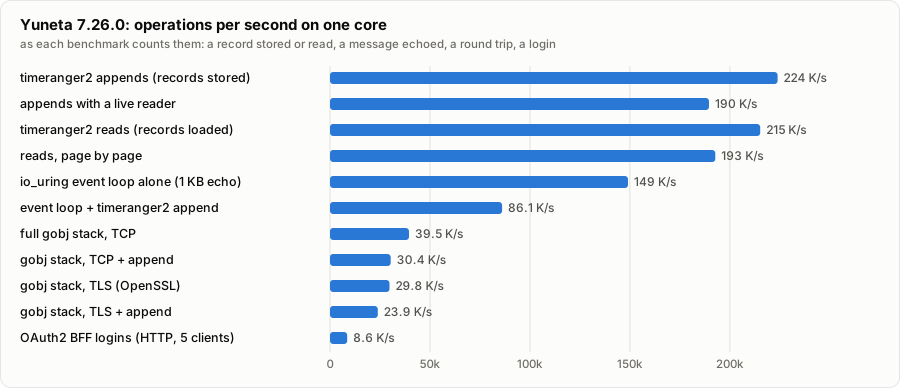
Operations per second on one core, as each benchmark counts them.
| Figure | Benchmark | 7.26.0 |
|---|---|---|
| Records stored per second, one key-indexed topic | test_topic_pkey_integer | 223,864 +- 12,198 |
| The same, with a live reader (an rt list) | test_topic_pkey_integer | 189,539 +- 7,784 |
| Records stored per second, one key, 600 000 appends | perf_timeranger2 tm_build_appends | 354,343 +- 10,491 |
| Records read per second, every record of 2 keys, one callback each | test_topic_pkey_integer_iterator2 | 215,157 +- 7,268 |
| Records read per second, page by page | test_topic_pkey_integer_iterator5 | 192,697 +- 4,480 |
| Open a store as master, 20 000 md2 files | perf_timeranger2 | 81.9 ms |
| A tm query of one minute of a key (every row read) | perf_timeranger2 | 12.8 ms |
| treedb: update a node in memory / saved | perf_tr_treedb | 2.49 us / 7.80 us |
| treedb: link or unlink / create / forced delete | perf_tr_treedb | 8.65 us / 65.6 us / 43.7 us |
| C_TREEDB: open 40 treedbs, schema unchanged | perf_c_treedb | 0.335 s |
| One log line of 300 bytes | perf_rotatory | 374 ns |
| One agent audit record / flushed | perf_rotatory | 570 ns / 1,257 ns |
| Event loop echo, 1 KB messages / with an append | perf_yev_ping_pong, perf_yev_ping_pong2 | 149.0 K / 86.1 K msg/s |
| gobj stack, TCP round trips / with an append | perf_tcp_test4, perf_tcp_test5 | 39,511 / 30,378 per s |
| gobj stack, TLS (OpenSSL 3.6.3) round trips / with an append | perf_tcps_test4, perf_tcps_test5 | 29,762 / 23,907 per s |
| OAuth2 BFF logins (HTTP, 5 clients, mock IdP) | perf_auth_bff | 8,622 per s |
| Binary size of a yuno, fully static with OpenSSL | outputs/yunos/* | 10.2-10.6 MB stripped, +0.04% to +0.15% against 7.25.22 |
7.25.22 against 7.25.21
7.25.22 closes two reviews -- of 7.25.21, and of the fixes made for it -- and the open defects of the list it inherited: the agents run as native systemd units; a connection can be dropped from any callback of TLS or TCP without a use of freed memory; a yuno alive but not connected can be killed; the rt_disk followers of timeranger2 hear what they used to lose; C_AUTHZ and the IdP stop handing roles and keys to whoever asks; a stats reset resets.
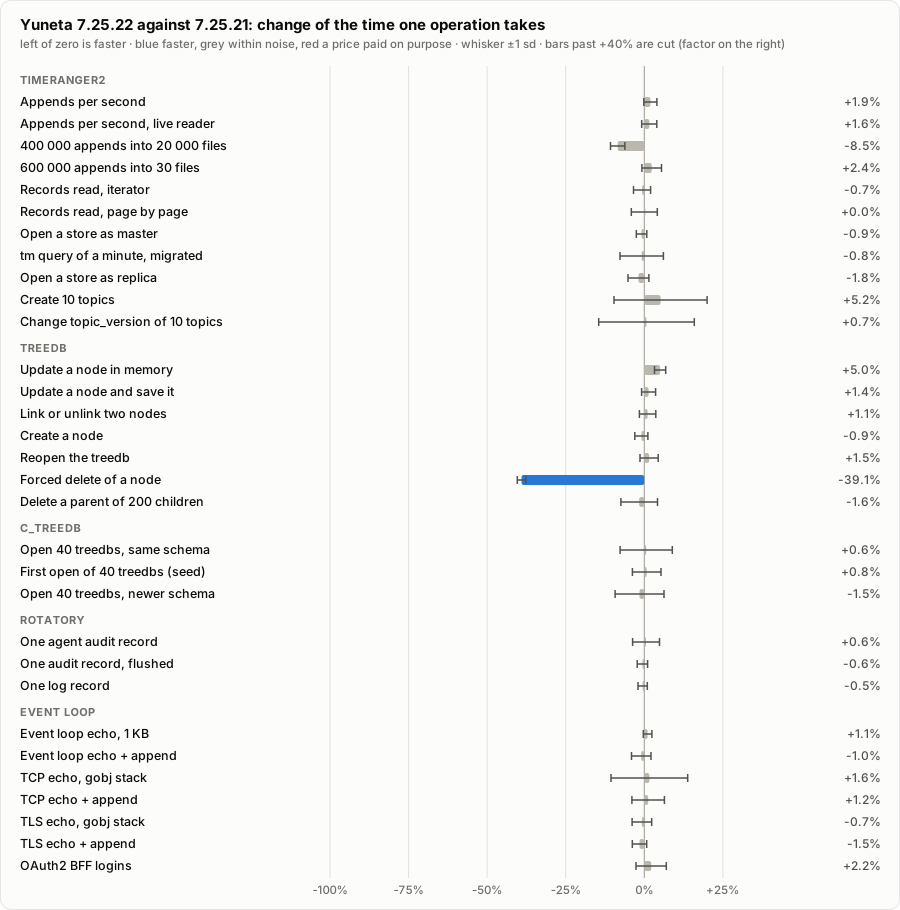
One bar per figure: the change of the time one operation takes, left of zero is faster. Blue is faster, grey is within the noise of its rounds, or placement.
| Faster | 7.25.21 | 7.25.22 | Change | Why |
|---|---|---|---|---|
| treedb: forced delete (2000 deletes, 100 000 nodes) | 69.8 us | 42.5 us | -39.1% (t = -62) | A delete no longer walks every key with an open file to close the descriptors of the one deleted. |
Four figures moved outside their spread on code that did not change in this release, and none is claimed:
| Moved | 7.25.21 | 7.25.22 | Change | Why it is not claimed |
|---|---|---|---|---|
Appends per second (test_topic_pkey_integer) | 228,532 | 224,185 | -1.9% (t = -4.6) | tranger2_append_record() and everything it calls are the same in both releases. |
| The same, with a live reader | 194,479 | 191,447 | -1.6% (t = -3.3) | The same append, and the rt_mem feed did not change. |
Appends to a store of many keys (build_appends) | 1,709 ms | 1,564 ms | -8.5% (t = -9.9) | The same append code, faster here and slower above. |
| treedb: update a node in memory | 2.30 us | 2.41 us | +5.0% (t = 8.2) | tr_treedb.c, kwid.c and jansson did not change; the gobj-c functions it could reach changed only in their trace branches. The same figure moved -5.2% the other way in the A/B of 7.25.21, on unchanged code too. |
Both releases are built whole, so the code lands at other addresses, which alone moves a figure by a few percent: that is placement, not speed, and it is said with its figure. The binaries are 0.4-0.5% larger (stripped).
The method: 7.25.21 and 7.25.22 each built from their own tree (a git worktree
of the 7.25.21 tag with the same .config and compiler, where only the kernel
libraries, modules/c/test, performance/c/ and the three ctest binaries were
built), the two binaries of each benchmark run alternately, the order flipped
every round, with a sync and a 3 s pause before each run: 8 rounds, 24 for
the three timeranger2 ctest binaries. outputs_ext was shared: linux-ext-libs
did not change.
What one machine does with 7.25.22
The 7.25.22 side of the same run: 8 rounds (24 for the ctest binaries), mean of the rounds, on the machine described below.
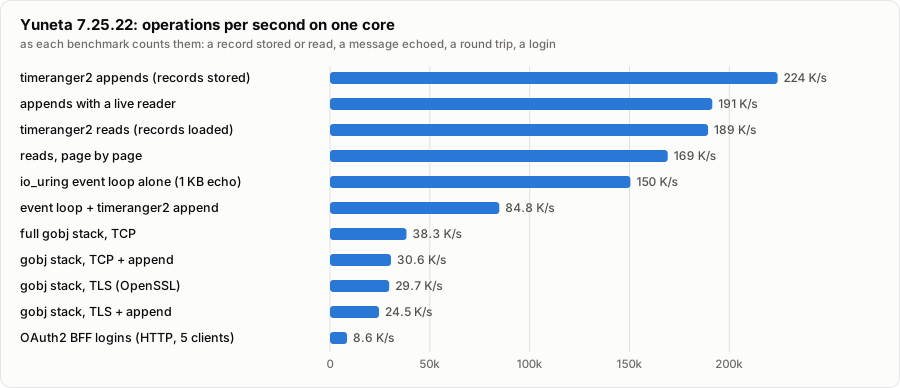
Operations per second on one core, as each benchmark counts them.
| Figure | Benchmark | 7.25.22 |
|---|---|---|
| Records stored per second, one key-indexed topic | test_topic_pkey_integer | 224,185 +- 3,339 |
| The same, with a live reader (an rt list) | test_topic_pkey_integer | 191,447 +- 3,677 |
| Records stored per second, one key, 600 000 appends | perf_timeranger2 tm_build_appends | 362,758 +- 6,468 |
| Records read per second, every record of 2 keys, one callback each | test_topic_pkey_integer_iterator2 | 189,390 +- 3,336 |
| Records read per second, page by page | test_topic_pkey_integer_iterator5 | 169,121 +- 3,810 |
| Open a store as master, 20 000 md2 files | perf_timeranger2 | 79.6 ms |
| A tm query of one minute of a key (migrated topic) | perf_timeranger2 | 7.47 ms |
| treedb: update a node in memory / saved | perf_tr_treedb | 2.41 us / 7.75 us |
| treedb: link or unlink / create / forced delete | perf_tr_treedb | 8.63 us / 63.3 us / 42.5 us |
| C_TREEDB: open 40 treedbs, schema unchanged | perf_c_treedb | 0.333 s |
| One log line of 300 bytes | perf_rotatory | 369 ns |
| One agent audit record / flushed | perf_rotatory | 568 ns / 1,232 ns |
| Event loop echo, 1 KB messages / with an append | perf_yev_ping_pong, perf_yev_ping_pong2 | 150.5 K / 84.8 K msg/s |
| gobj stack, TCP round trips / with an append | perf_tcp_test4, perf_tcp_test5 | 38,292 / 30,571 per s |
| gobj stack, TLS (OpenSSL 3.6.3) round trips / with an append | perf_tcps_test4, perf_tcps_test5 | 29,663 / 24,528 per s |
| OAuth2 BFF logins (HTTP, 5 clients, mock IdP) | perf_auth_bff | 8,581 per s |
| Binary size of a yuno, fully static with OpenSSL | outputs/yunos/* | 10.2-10.6 MB stripped, +0.4% to +0.5% against 7.25.21 |
7.25.21 against 7.25.20
7.25.21 is a security and correctness release: credentials are masked in
every trace, in every kw the kernel dumps, in the traffic dumps and in
view-config; a gbuffer can be marked secret (hidden from the dumps, wiped
when it is freed, never serialized); C_TCP and C_TCP_S stop and start
again cleanly and count their connections; the rt_disk feeds of timeranger2
hear every delete. None of it is on the paths that run every second at the
default trace levels: the masking runs only when a trace prints. On those
paths a secret gbuffer costs the test of one flag, and a TCP send one key
lookup (the __secret__ flag of EV_TX_DATA).
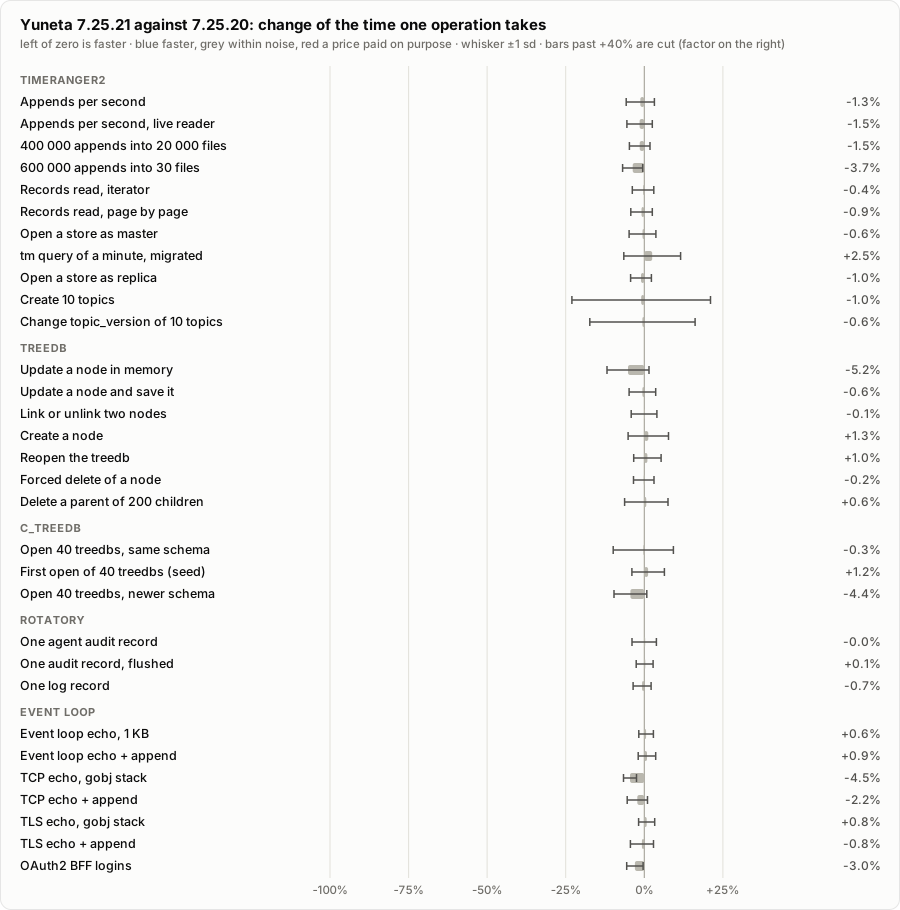
One bar per figure: the change of the time one operation takes, left of zero is faster. Grey is within the noise of its rounds, or placement. No bar is red: nothing is slower beyond its noise, and no bar is blue: nothing is claimed faster.
Nothing got slower beyond the spread of its rounds. Three figures moved outside it, all of them faster, and none is claimed as a gain:
| Moved | 7.25.20 | 7.25.21 | Change | Why it is not claimed |
|---|---|---|---|---|
| TCP echo through the gobj stack | 37,909 | 39,715 round trips/s | +4.8% (t = 6.2) | No change takes work off this path (a TCP send gained a key lookup), and the TLS echo, which runs the same C_TCP code, did not move (-0.7%). |
| OAuth2 BFF logins | 8,350 | 8,606 per s | +3.1% (t = 3.2) | c_auth_bff.c changed by one line; the HTTP path did not change. |
600 000 appends to one key (tm_build_appends) | 1,720 | 1,656 ms | -3.7% (t = -3.2) | tranger2_append_record() is the same in both releases; the same benchmark moved +3.6% the other way in the 7.25.20 report. |
Both releases are built whole, so the code lands at other addresses, which
alone moves a figure by a few percent (2.5% on an append, measured for
7.25.5): that is placement, not speed. The main append benchmark,
test_topic_pkey_integer, 24 rounds, moved +1.3% (223,031 -> 225,883
appends/s), inside its spread. The binaries are 0.6-0.9% larger (stripped),
the code of the masking.
The method: 7.25.20 and 7.25.21 each built from their own tree (a git
worktree of the 7.25.20 tag with the same .config and compiler, where only
the kernel libraries, modules/c/test, performance/c/ and the three ctest
binaries were built), the two binaries of each benchmark run alternately, the
order flipped every round, with a sync and a 3 s pause before each run: 8
rounds, 24 for the three timeranger2 ctest binaries. outputs_ext was shared:
linux-ext-libs moved from 1.22 to 1.23 in this release, but only in how
openresty is downloaded, and no library changed version.
What one machine does with 7.25.21
The benchmarks of performance/c/ on the build of 7.25.21 at tag time, 5
rounds; the appends and reads of the ctest binaries are the 7.25.21 side of
the A/B run (24 rounds). Mean of the rounds, on the machine described below.
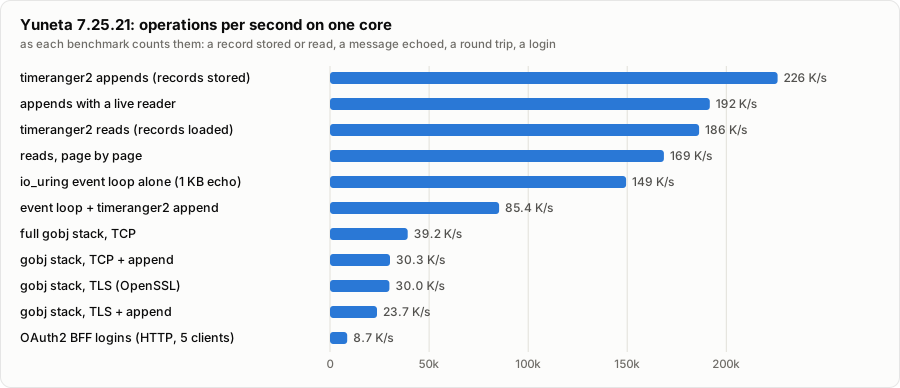
Operations per second on one core, as each benchmark counts them.
| Figure | Benchmark | 7.25.21 |
|---|---|---|
| Records stored per second, one key-indexed topic | test_topic_pkey_integer | 225,883 +- 6,043 |
| The same, with a live reader (an rt list) | test_topic_pkey_integer | 191,672 +- 5,799 |
| Records stored per second, one key, 600 000 appends | perf_timeranger2 tm_build_appends | 365,419 +- 10,488 |
| Records read per second, every record of 2 keys, one callback each | test_topic_pkey_integer_iterator2 | 186,284 +- 4,672 |
| Records read per second, page by page | test_topic_pkey_integer_iterator5 | 168,516 +- 3,912 |
| Open a store as master, 20 000 md2 files | perf_timeranger2 | 80.1 ms |
| A tm query of one minute of a key (migrated topic) | perf_timeranger2 | 7.50 ms |
| treedb: update a node in memory / saved | perf_tr_treedb | 2.31 us / 7.74 us |
| treedb: link or unlink / create / forced delete | perf_tr_treedb | 8.68 us / 64.4 us / 69.3 us |
| C_TREEDB: open 40 treedbs, schema unchanged | perf_c_treedb | 0.327 s |
| One log line of 300 bytes | perf_rotatory | 372 ns |
| One agent audit record / flushed | perf_rotatory | 582 ns / 1,230 ns |
| Event loop echo, 1 KB messages / with an append | perf_yev_ping_pong, perf_yev_ping_pong2 | 149.4 K / 85.4 K msg/s |
| gobj stack, TCP round trips / with an append | perf_tcp_test4, perf_tcp_test5 | 39,231 / 30,273 per s |
| gobj stack, TLS (OpenSSL 3.6.3) round trips / with an append | perf_tcps_test4, perf_tcps_test5 | 29,999 / 23,718 per s |
| OAuth2 BFF logins (HTTP, 5 clients, mock IdP) | perf_auth_bff | 8,660 per s |
| Binary size of a yuno, fully static with OpenSSL | outputs/yunos/* | 10.2-10.5 MB stripped, +0.6% to +0.9% against 7.25.20 |
7.25.20 against 7.25.5
The fifteen releases between the two reports fixed the agent, the file
watcher, the TCP writes, the SWITCHS macro and the masking of secrets. None
of them was meant to change speed, and one of them is the largest gain of the
round: since 7.25.7 SWITCHS no longer compiles a regular expression each
time a switch is entered (it leaked it on every return from a case, commit
3e8ff0508). tr_treedb switches on the type of every column, so every
treedb write paid a regcomp(".*") and a regfree; tr_treedb.c and
c_treedb.c did not change between the two releases.
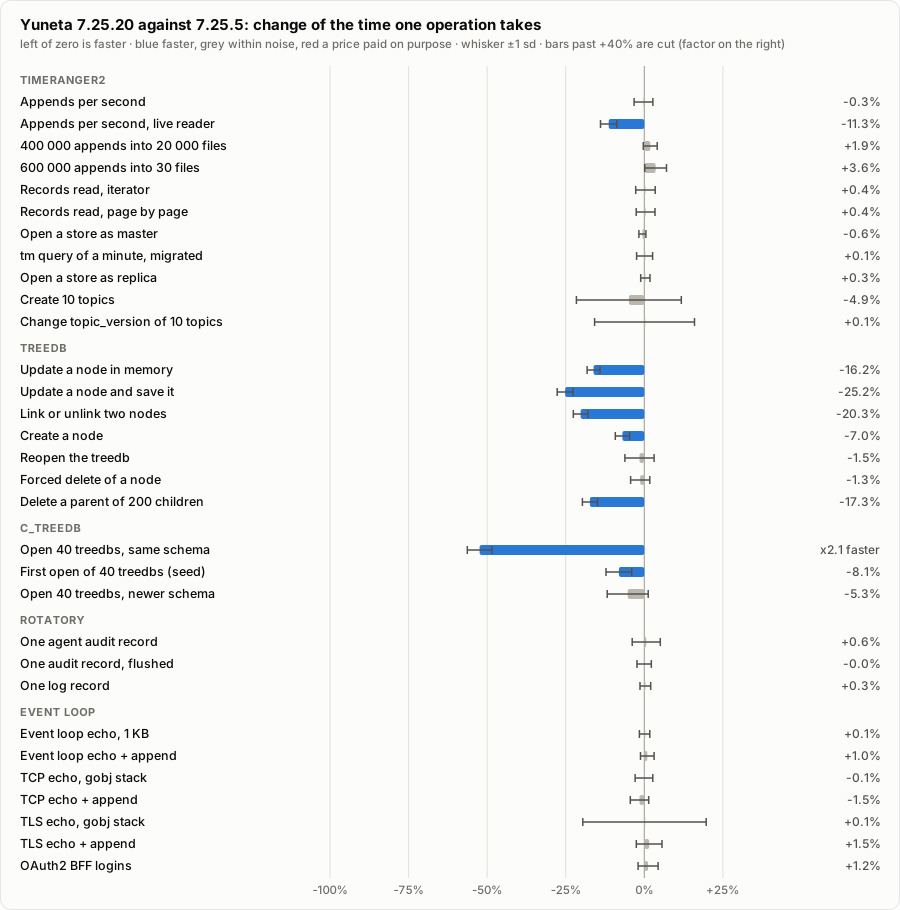
One bar per figure: the change of the time one operation takes, left of zero is faster. Blue is faster, grey is within the noise of its rounds. No bar is red: nothing is slower beyond its noise.
| Faster | 7.25.5 | 7.25.20 | Change | Why |
|---|---|---|---|---|
| C_TREEDB: open 40 treedbs, schema unchanged | 0.667 s | 0.318 s | x2.1 | SWITCHS: the open checks every column of each schema and loads every node through those switches. |
| treedb: update a node and save it | 10.25 us | 7.66 us | -25.2% | SWITCHS in the validation of each column. |
| treedb: link or unlink two nodes | 10.85 us | 8.65 us | -20.3% | The same. |
| treedb: forced delete of a parent with 200 children | 2,996 us | 2,478 us | -17.3% | The same. |
| treedb: update a node in memory | 2.76 us | 2.32 us | -16.2% | The same. |
| Appends per second with a live reader | 169,624 | 191,284 | +12.8% | The benchmark’s own rt callback switches on the key with SWITCHS once per record: the fix seen from a caller. timeranger2’s rt path did not change. |
| C_TREEDB: first open of 40 treedbs (seed) | 11.09 s | 10.19 s | -8.1% | SWITCHS. |
| treedb: create a node | 69.7 us | 64.9 us | -7.0% | SWITCHS. |
Nothing got slower beyond the spread of its rounds. The closest,
tm_build_appends (600 000 appends to one key, 1,632 -> 1,691 ms, +3.6%, at
the edge of the spread), runs append code that is the same in both releases:
timeranger2.c changed only in its rt-disk rescan. Both releases are built
whole, so the code lands at other addresses, which alone moves an append by up
to 2.5% (measured for 7.25.5); the main append benchmark,
test_topic_pkey_integer, 24 rounds, moved +0.3%.
The method: 7.25.5 and 7.25.20 each built whole from their own tree (a git
worktree of the tag for 7.25.5; the same .config, compiler and external
libraries), the two binaries of each benchmark run alternately, the order
flipped every round, with a sync and a 3 s pause before each run: 8 rounds,
24 for the three timeranger2 ctest binaries.
What one machine does with 7.25.20
The 7.25.20 side of the same run: 8 rounds (24 for the ctest binaries), mean of the rounds, on the machine described below.
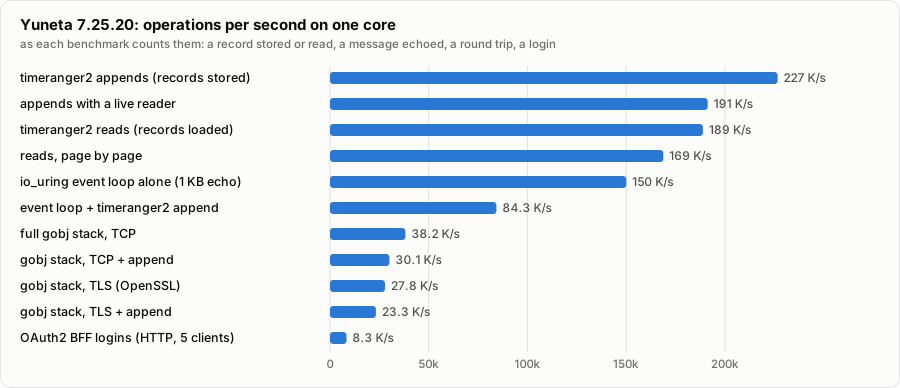
Operations per second on one core, as each benchmark counts them.
| Figure | Benchmark | 7.25.20 |
|---|---|---|
| Records stored per second, one key-indexed topic | test_topic_pkey_integer | 226,720 +- 4,468 |
| The same, with a live reader (an rt list) | test_topic_pkey_integer | 191,284 +- 4,132 |
| Records stored per second, one key, 600 000 appends | perf_timeranger2 tm_build_appends | 355,059 +- 8,509 |
| Records read per second, every record of 2 keys, one callback each | test_topic_pkey_integer_iterator2 | 188,895 +- 4,283 |
| Records read per second, page by page | test_topic_pkey_integer_iterator5 | 168,796 +- 3,212 |
| Open a store as master, 20 000 md2 files | perf_timeranger2 | 78.2 ms |
| A tm query of one minute of a key (migrated topic) | perf_timeranger2 | 7.35 ms |
| treedb: update a node in memory / saved | perf_tr_treedb | 2.32 us / 7.66 us |
| treedb: link or unlink / create / forced delete | perf_tr_treedb | 8.65 us / 64.9 us / 68.5 us |
| C_TREEDB: open 40 treedbs, schema unchanged | perf_c_treedb | 0.318 s |
| One log line of 300 bytes | perf_rotatory | 375 ns |
| One agent audit record / flushed | perf_rotatory | 572 ns / 1,244 ns |
| Event loop echo, 1 KB messages / with an append | perf_yev_ping_pong, perf_yev_ping_pong2 | 150.1 K / 84.3 K msg/s |
| gobj stack, TCP round trips / with an append | perf_tcp_test4, perf_tcp_test5 | 38,191 / 30,073 per s |
| gobj stack, TLS (OpenSSL 3.6.3) round trips / with an append | perf_tcps_test4, perf_tcps_test5 | 27,849 / 23,271 per s |
| OAuth2 BFF logins (HTTP, 5 clients, mock IdP) | perf_auth_bff | 8,347 per s |
| Binary size of a yuno, fully static with OpenSSL | outputs/yunos/* | 10.1-10.4 MB stripped, as 7.25.5 (+0.1% to +0.4%) |
7.25.5 against 7.25.4
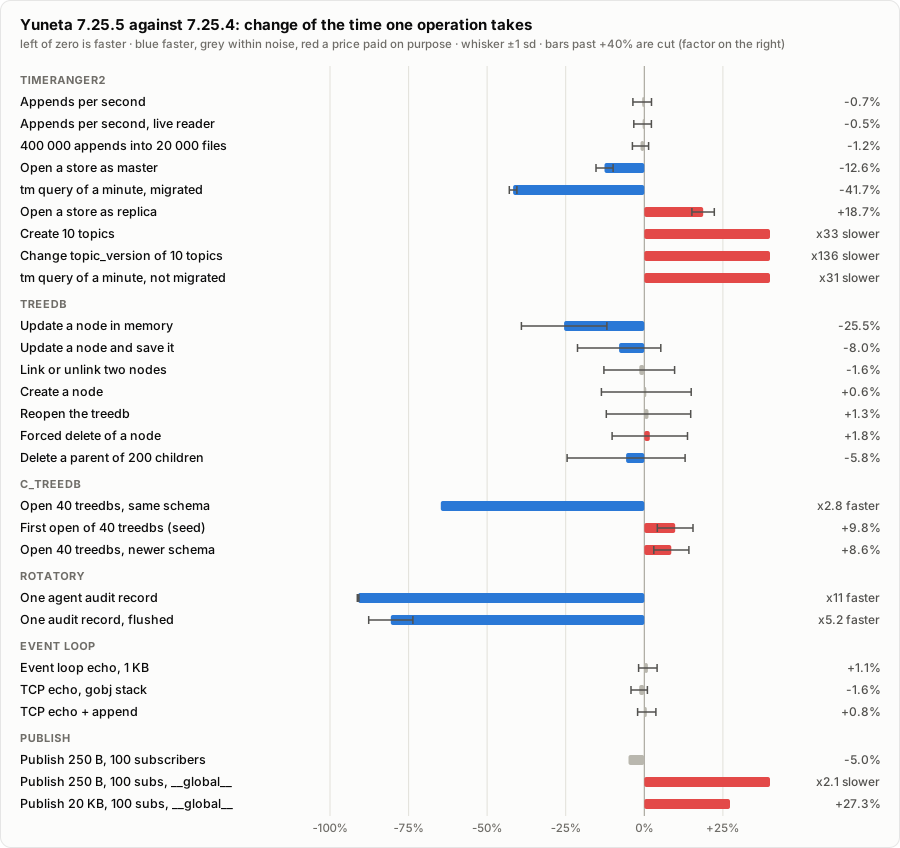
One bar per figure: the change of the time one operation takes (a rate is turned into time per operation), left of zero is faster. Blue is faster, grey is within the noise of its rounds, red is slower and kept by decision.
The prices of 7.25.5, and what each one buys:
| Slower | By | Why |
|---|---|---|
| Create a topic (timeranger2) | 3.6 -> 118.9 ms for 10 | 2 fsyncs per topic: a power cut never leaves a topic whose files are not on disk. |
Change a topic_version | 1.7 -> 231.5 ms for 10 | 4 fsyncs per change: never a new topic_version over a topic_cols.json that is not on disk. |
| A tm query on a topic of 7.25.4 or earlier | 12.7 -> 391.6 ms | Until mark-tm-order migrates the topic (19 ms, once): the old topic does not say that its tm order holds. After the migration the query takes 7.4 ms. (From 7.26.0 the tm markers and mark-tm-order are gone: a tm query is a filter on every row again; with 7.26.0’s block reads and once-parsed condition it takes ~12.8 ms on the benchmark’s store, where a topic marked by 7.25.5..7.25.22 took 7.5 ms.) |
| Open a store as a replica | 89.7 -> 106.5 ms | One more stat() per md2 file: a replica looks for the order markers after reading each file, so it cannot miss one the master writes during the open. |
| C_TREEDB: first open, newer schema | +10%, +9% | The record of the projection in progress, written whole with its fsyncs: a crash in the middle is finished at the next open. |
Publish with __global__ or __local__ | +0.23 us a delivery | Each such subscription gets its own kw_twin() of the event, so a peer’s subscription cannot change the event of every later subscriber. Every remote (C_IEVENT_SRV) subscription carries __global__. |
| treedb forced delete | +1.8% (~1 us) | The delete holds its events and keeps the column that lets a refused delete change nothing. |
| The agent audit record, built | +2-3% | Names are judged with their JSON escapes decoded, and a write-attr is looked for in every string: no secret reaches the audit file. |
Every A/B of 7.25.5, change by change, with its rounds and spread, is in
performance/c/README.md
and in the CHANGELOG (“Performance, against 7.25.4”).
What one machine does with 7.25.5
Measured at tag time on the build of 7.25.5: 5 rounds (3 for perf_c_treedb
and perf_auth_bff), mean of the rounds. One process; the event loop runs on
one core, and Yuneta scales by running one yuno per core.
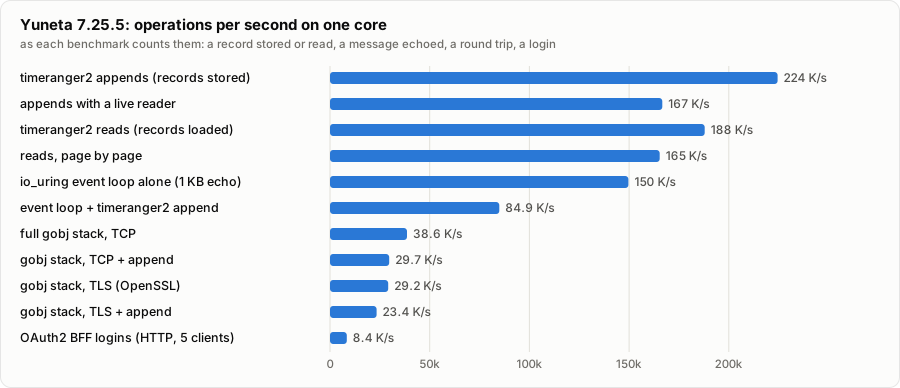
Operations per second on one core, as each benchmark counts them: a record stored or read, a message echoed, a round trip, a login.
| Figure | Benchmark | 7.25.5 |
|---|---|---|
| Records stored per second, one key-indexed topic | test_topic_pkey_integer | 224,455 +- 2,585 |
| The same, with a live reader (an rt list) | test_topic_pkey_integer | 166,654 +- 1,748 |
| Records stored per second, one key, 600 000 appends | perf_timeranger2 tm_build_appends | 365,459 +- 5,836 |
| Records read per second, every record of 2 keys, one callback each | test_topic_pkey_integer_iterator2 | 187,914 +- 3,379 |
| Records read per second, page by page | test_topic_pkey_integer_iterator5 | 165,301 +- 1,971 |
| Open a store as master, 20 000 md2 files | perf_timeranger2 | 79.8 ms |
| A tm query of one minute of a key (migrated topic) | perf_timeranger2 | 7.2 ms |
| treedb: update a node in memory / saved | perf_tr_treedb | 2.76 us / 10.37 us |
| treedb: link or unlink / create / forced delete | perf_tr_treedb | 11.02 us / 71.0 us / 69.2 us |
| C_TREEDB: open 40 treedbs, schema unchanged | perf_c_treedb | 0.649 s |
| One log line of 300 bytes | perf_rotatory | 381 ns |
| One agent audit record / flushed | perf_rotatory | 570 ns / 1,263 ns |
| Event loop echo, 1 KB messages / with an append | perf_yev_ping_pong, perf_yev_ping_pong2 | 149.6 K / 84.9 K msg/s |
| gobj stack, TCP round trips / with an append | perf_tcp_test4, perf_tcp_test5 | 38,587 / 29,699 per s |
| gobj stack, TLS (OpenSSL 3.6.3) round trips / with an append | perf_tcps_test4, perf_tcps_test5 | 29,166 / 23,363 per s |
| OAuth2 BFF logins (HTTP, 5 clients, mock IdP) | perf_auth_bff | 8,446 per s |
| Binary size of a yuno, fully static with OpenSSL | outputs/yunos/* | 10.1-10.4 MB stripped, 33.9-34.7 MB with debug information |
TLS with OpenSSL costs 24% of the round trips of plain TCP through the gobj stack (29,166 against 38,587). mbedTLS is not built on the measuring machine, so its figures are not in the report.
How the figures are measured
The machine. One laptop, the same for every report until a report says otherwise: an Acer Nitro AN517-53 with an 11th Gen Intel Core i7-11370H (4 cores, 8 threads, up to 4.8 GHz), 31 GiB of RAM, a Samsung 990 PRO NVMe with ext4, Linux 7.0.0-34-generic, Ubuntu 26.04.1 LTS, glibc 2.43, gcc 15.2.0. Absolute figures compare only between reports of the same machine.
The build. RelWithDebInfo (
-O2 -g), gcc, fully static, OpenSSL, withCONFIG_DEBUG_TRACK_MEMORYon (every allocation is tracked).A/B. The module of the old release is compiled with the headers of the new one and linked before the same libraries; the two binaries run alternately, with a
syncand a pause before each run. For timeranger2 the modules are padded to one size and linked four times at four addresses, because the address of the libraries alone moves an append by up to 2.5%. That is the A/B of 7.25.5. The A/B of 7.25.20 and of 7.25.21 builds each release whole from its own tree and runs the two binaries alternately, the order flipped every round: simpler, and blind to a change under ~2.5% on an append, which it says where it matters.Tag time. The benchmarks of
performance/c/, in rounds, on the build of the release.
The benchmarks themselves are described in Benchmarks & Stress Tests.